Structured latent space
A continuous three-stream representation separately models upper-body, lower-body, and expression dynamics.
SIGGRAPH Asia 2026
Stony Brook University · Futurewei Technologies Inc.
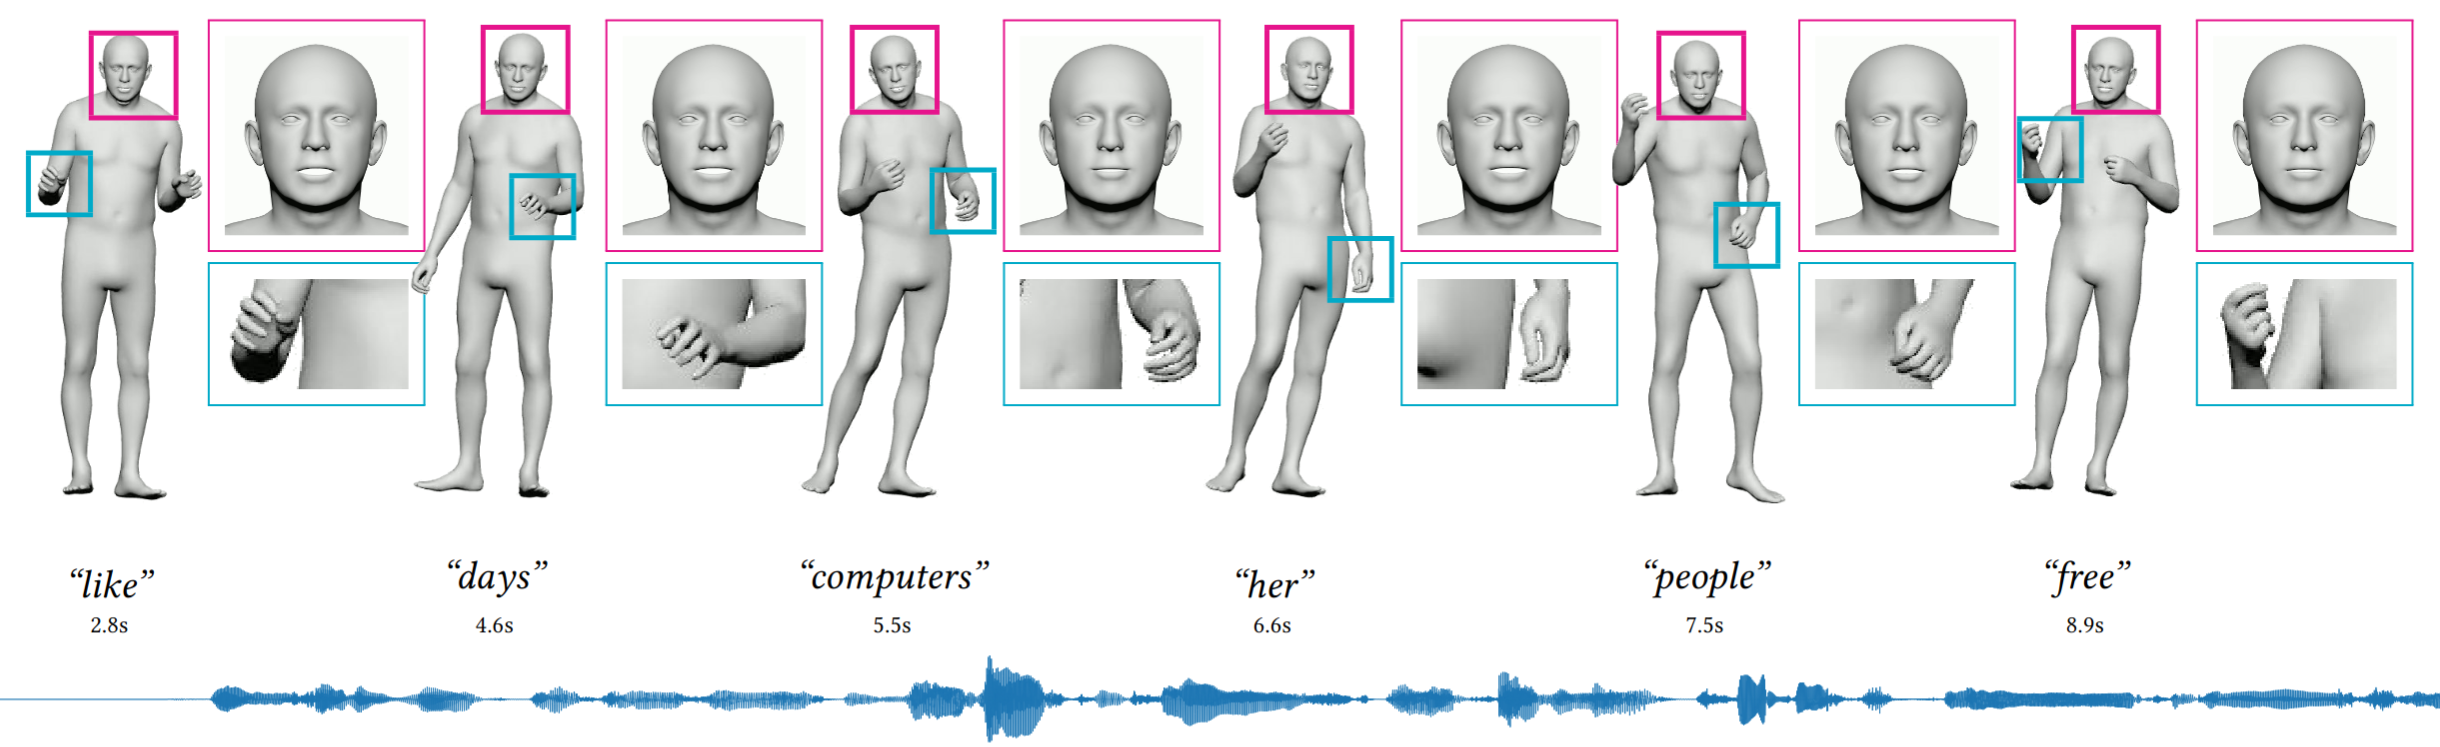
Holistic co-speech motion generation aims to synthesize coordinated facial expressions, hand gestures, and body movements from speech, which is challenging due to heterogeneous part-specific dynamics, long-range temporal coherence, and cross-part coordination. Directly modeling high-dimensional motion can be unstable, while overly compact or unstructured latent spaces may lose fine-grained motion details.
We present TalkFlow, a structured latent flow framework for speech-driven holistic motion generation. TalkFlow learns a continuous three-stream latent representation for upper-body motion, lower-body motion, and facial expressions, preserving part-specific dynamics without forcing heterogeneous motion components into a single latent space. Lightweight cross-stream interactions maintain holistic coordination during both latent representation learning and flow-based generation.
Conditioned on multi-level speech features, TalkFlow performs speech-conditioned latent flow matching and learns a continuous transport process from source latents to realistic motion latents. Experiments on BEAT2 demonstrate strong facial fidelity, competitive body-motion quality, and effective speech-motion synchronization.
A continuous three-stream representation separately models upper-body, lower-body, and expression dynamics.
Lightweight FiLM-gated interactions coordinate heterogeneous motion streams while preserving part-specific behavior.
Branch-specific speech conditions guide efficient continuous transport in the learned motion latent space.
Read the complete 12-page SIGGRAPH Asia 2026 conference paper directly below. The PDF is available here while the publisher's DOI landing page is being updated.
Checking paper availability…
Five complete BEAT2 test sequences comparing holistic co-speech motion generation. Each video retains its original method labels, side-by-side layout, and speech audio. For the clearest view of expressions and gestures, open a video at full resolution.
@inproceedings{talkflow2026,
  title     = {TalkFlow: Structured Latent Flow Matching for
               Speech-Driven Holistic Motion Generation},
  author    = {Xinmu Wang and Fumi Honda and Xiang Gao and Xianfeng Gu and Xiyun Song and Heather Yu},
  booktitle = {SIGGRAPH Asia 2026 Conference Papers},
  year      = {2026},
  doi       = {10.1145/3829340.3842366}
}